Hands-on AI testingGenerating test cases with Dify
Generating test cases with Dify
Lesson 1 · Yoyo本慢 · 搭一个小应用,把需求变成用例
Free series you watch on this site, no sign-in. Video is served by Bilibili; lessons are in Chinese.
Not translated yet — showing the Chinese originals.
16 lessons
Public Bilibili videos you watch on this site. Twelve authors, each on one concrete job: writing cases, driving automation, and load-testing a model.
For:Test engineers who already use a model to write cases or scripts and want to see how other people do it.
16 lessons
Lesson 1 · Yoyo本慢 · 搭一个小应用,把需求变成用例
Lesson 2 · 任我御风而行 · 从安装到导出一份用例表
Lesson 3 · 清风说测试开发 · 生成之后,人还要看的地方
Lesson 4 · Hyowinner校长 · 拿一条逻辑,看它覆盖得怎么样
Lesson 5 · 严师兄聊AI · 把写测试收成一条命令
Lesson 6 · Raina测试 · 规则写对,生成的结果才稳
Lesson 7 · 向度之桥 · 让 Claude Code 自己点页面
Lesson 8 · 测试避坑君 · 从安装到把一条流程跑起来
Lesson 9 · Zhu的AI日记 · 在 Cursor 里测一个 App
Lesson 10 · 西瓜讲大模型 · 并发上去之后先看什么
Lesson 11 · 小工蚁创始人 · 一个开源的模型压测工具
Lesson 12 · AIGC科技官 · 压测的同时看监控
Lesson 13 · 每日学编程 · 单集标题是 EvalScope 压力测试,讲的是压测,不是评测指标概述。
Lesson 14 · swanmsg · 简介指向 vLLM 项目下的 GuideLLM 仓库,讲部署后的基准测试。
Lesson 15 · 但问智能 · Feed requirements and schemas to an Agent that generates, diagnoses, and repairs API, performance, and UI tests.
Lesson 16 · Qoder · 通过 Qoder 的实际演示,了解 AI 编程工具如何辅助测试工作提效。
45 lessons · 学掌门
How AI evaluation differs from software testing, how to score and grade defects, then how to run batch evals with EvalScope and Langfuse.
For:Testers and engineers who need to accept a model or an agent, not just demo it.
45 lessons
Lesson 1 · 学掌门 · Separate the thing you measure from a pass-fail feature check.
Lesson 2 · 学掌门 · Software tests want a fixed result. Model evals want a stable, repeatable one.
Lesson 3 · 学掌门 · Look at which class the errors fall into before trusting one score.
Lesson 4 · 学掌门 · Data, metric, then a conclusion you can rerun.
Lesson 5 · 学掌门 · Name the four objects before comparing scores.
Lesson 6 · 学掌门 · Find what would invalidate the whole run before comparing scores.
Lesson 7 · 学掌门 · A finding needs a grade before it can become a defect.
Lesson 8 · 学掌门 · One manual try hides regressions. A batch does not.
Lesson 9 · 学掌门 · Only for the lab environment. Skip it if Docker already runs.
Lesson 10 · 学掌门 · Both tools in this course run from this container setup.
Lesson 11 · 学掌门 · Keep inputs, outputs, and scores. A terminal log is not a record.
Lesson 12 · 学掌门 · Connect datasets and metrics instead of a one-off script.
Lesson 13 · 学掌门 · Review each row, not only the aggregate.
Lesson 14 · 学掌门 · Run the batch and read the metric.
Lesson 15 · 学掌门 · Rerun it, compare it, and point at the failing rows.
Lesson 16 · 每日学编程 · 单集标题是 EvalScope 概述,只讲这个工具在测什么,不讲后面的压力测试。
Lesson 17 · 前端屎不了 · 简介写了从 Observation、Trace、Session 讲到 Evals、Datasets 和 Metrics。
Lesson 18 · 科罗廖夫的雪松 · 简介里作者用它和 RAGAS 对比,想把上一轮结果拿来做卡点。
Lesson 19 · THUAIR_人机交互研究组 · 简介写的是 Nature 论文:用语义熵检测大语言模型幻觉。
Lesson 20 · 熊二等兵 · Combine final success rate with intermediate checkpoints to locate failures in long-horizon agent tasks.
Lesson 21 · 卡比Prover · 先沿执行轨迹看清 Agent 做了什么,再决定在哪些节点设置评测。
Lesson 22 · 慢学AI · 围绕 Agent 评估设计评分器,把结果判断从主观感觉变成明确规则。
Lesson 23 · 量子菠萝_ · 从 Trace、失败归因和评分器一路做到自动化实验,验证提示词改动是否真的有效。
Lesson 24 · 源语AI-摸鱼字幕君 · Build a production eval loop from offline simulation and quality gates to online monitoring, grounded in whether the task was actually completed.
Lesson 25 · 西瓜讲大模型 · Follow a complete demonstration to understand the Agent evaluation workflow end to end.
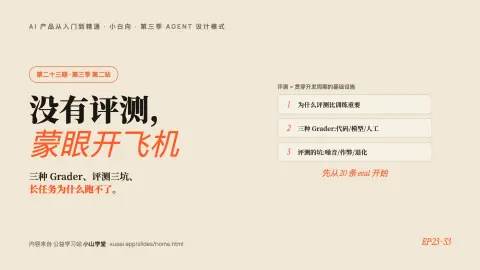
Lesson 26 · wanzij177 · Compare code, model, and human graders, then examine noise, gaming, and premature completion in long tasks.
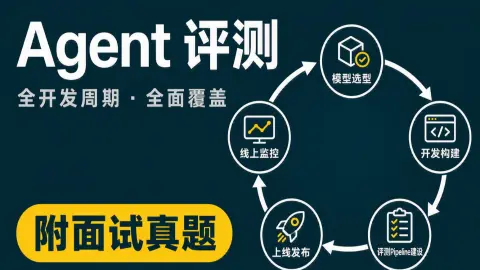
Lesson 27 · 不转到大模型不改名 · Follow Agent evaluation from model selection and integration testing to pipelines and production monitoring.
Lesson 28 · AI老马啊 · Organize Agent targets, datasets, and execution into an automated evaluation system.
Lesson 29 · AIOps智能运维 · Separate model quality, system usability, user adoption, and business value, then ground them with a Golden Set and tool correctness.
Lesson 30 · 慢学AI · Understand why evaluation is the foundation for stable iteration and scale.
Lesson 31 · 慢学AI · Use explicit graders instead of relying on subjective impressions.
Lesson 32 · 慢学AI · Separate occasional success from consistent success across repeated runs.
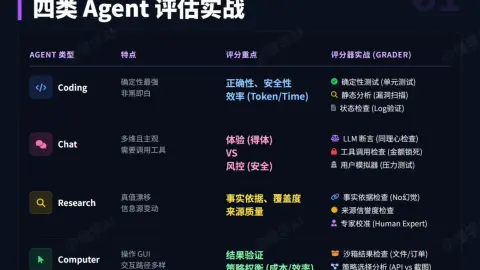
Lesson 33 · 慢学AI · Match grader priorities to the type of Agent and its task.
Lesson 34 · 慢学AI · Organize targets, data, and grading into a repeatable evaluation system.
Lesson 35 · 慢学AI · Extend offline evaluation with continuous production monitoring.
Lesson 36 · 高楼_Zee · 从工具定位入手,建立 EvalScope 与大模型评测流程的基础认识。
Lesson 37 · 慢学AI · Choose between a custom eval stack and an existing framework based on isolation, monitoring, and data requirements.
Lesson 38 · GPT中英字幕课程资源 · Evaluate effectiveness, hallucination, and bias, then use the results to iterate and monitor an Agent in production.
Lesson 39 · 肖恩君Sean · Connect run traces, Langfuse tracking, and LLM-as-judge evaluation into a repair loop.
Lesson 40 · 丸一口 · Read the paper and code behind a framework designed to evaluate LLM Agent capabilities.
Lesson 41 · ShiianAI · Run a RAG evaluation from data preparation to visualization and inspect individual samples.
Lesson 42 · 丹哥二号 · Apply an evaluation framework to load-test a model
Lesson 43 · poyhh · Replace subjective acceptance with metrics and tests
Lesson 44 · TreeDy1 · Understand Agent evaluation through Task, Grader, and Harness
Lesson 45 · David鲍曼 · Bring LLM evaluation into a Python implementation
11 lessons · 骰子AI
A public multi-part video that walks through RAGAS metrics in order: similarity, relevance, context precision, recall, faithfulness, correctness, and aspect critique.
For:People running retrieval-augmented apps who need to see which part of an answer is unsupported.
11 lessons
Lesson 1 · 骰子AI · 这一集标题是概览,先把后面要拆的指标摆出来。
Lesson 2 · 骰子AI · 分 P 标题是 Answer Similarity,讲答案和参考答案像不像。
Lesson 3 · 骰子AI · 分 P 标题是 Answer Relevance,讲回答是否扣住问题。
Lesson 4 · 骰子AI · 分 P 标题是 Context Precision。
Lesson 5 · 骰子AI · 分 P 标题是 Context Relevance。
Lesson 6 · 骰子AI · 分 P 标题是 context recall。
Lesson 7 · 骰子AI · 分 P 标题写的就是 context recall 在 RAGAS 里的坑。
Lesson 8 · 骰子AI · 分 P 标题是 Faithfulness。
Lesson 9 · 骰子AI · 分 P 标题是 Answer Correctness。
Lesson 10 · 骰子AI · 分 P 标题是 Aspect Critique。
Lesson 11 · 骰子AI · 最后一集标题是总结。
2 lessons · OpenMMLab
Two separate public lessons from OpenMMLab: how OpenCompass organizes an evaluation, then a hands-on run. Not a model leaderboard.
For:Testers and engineers who need to run a benchmark, not read a ranking.
2 lessons
Lesson 1 · OpenMMLab · 官方教程这一集讲 OpenCompass 大模型评测,简介里给了教程文档和仓库。
Lesson 2 · OpenMMLab · 贡献者讲的实战课,简介里给了课程文档和作业仓库。
5 lessons · 但问智能
Learn a reusable AI test-case workflow: use a vision LLM to read mind maps, flowcharts, and UI screens, generate cases, and export the result.
For:Test engineers who want to apply vision LLMs to test-case design or build an AI testing agent.
5 lessons
Lesson 1 · 但问智能 · Follow the full path from mind maps, flowcharts, and UI screens to generated and exported test cases.
Lesson 2 · 但问智能 · Ground the model in business knowledge instead of relying on a one-off prompt.
Lesson 3 · 但问智能 · Implement the generation logic and agent workflow as a complete test-case automation application.
Lesson 4 · 但问智能 · Use a structured agent to turn large-scale test-case generation into a controlled engineering workflow.
Lesson 5 · 但问智能 · Connect natural language, UI understanding, Playwright, and visual reports to execute and debug UI tests.
9 lessons · 大云哥讲AI
A nine-part path through AI application evaluation: metrics, datasets, evaluators, Agent and RAG evaluation, and a practical LangSmith workflow.
For:Testers and engineers building AI applications, Agents, or RAG systems who need repeatable evaluations.
9 lessons
Lesson 1 · 大云哥讲AI · Establish the objects, workflow, and conclusions of an evaluation.
Lesson 2 · 大云哥讲AI · Turn the capability you want to observe into measurable metrics.
Lesson 3 · 大云哥讲AI · Prepare data that supports repeatable runs and comparisons.
Lesson 4 · 大云哥讲AI · Move from choosing evaluators to running an actual evaluation.
Lesson 5 · 大云哥讲AI · Evaluate an Agent through its behavior and outcomes.
Lesson 6 · 大云哥讲AI · Break RAG answer quality into evaluable questions.
Lesson 7 · 大云哥讲AI · Connect the metrics, dataset, and evaluator in LangSmith.
Lesson 8 · 大云哥讲AI · Run a complete evaluation on an LLM application.
Lesson 9 · 大云哥讲AI · Apply the evaluation workflow to a running RAG application.
2 lessons · 森_MS
Build a practical Agent evaluation line across hallucination, empty-answer, satisfaction, token cost, TTFB, and escalation metrics, using reproducible log-based measurement.
For:Testers, engineers, and product teams who need measurable Agent quality signals for acceptance and production monitoring.
2 lessons
Lesson 1 · 森_MS · Break Agent quality into measurable signals across hallucination, satisfaction, latency, cost, and escalation.
Lesson 2 · 森_MS · Close the practical walkthrough with a short supplement on the same Agent metrics.